Turn Raw Data into Clear Answers
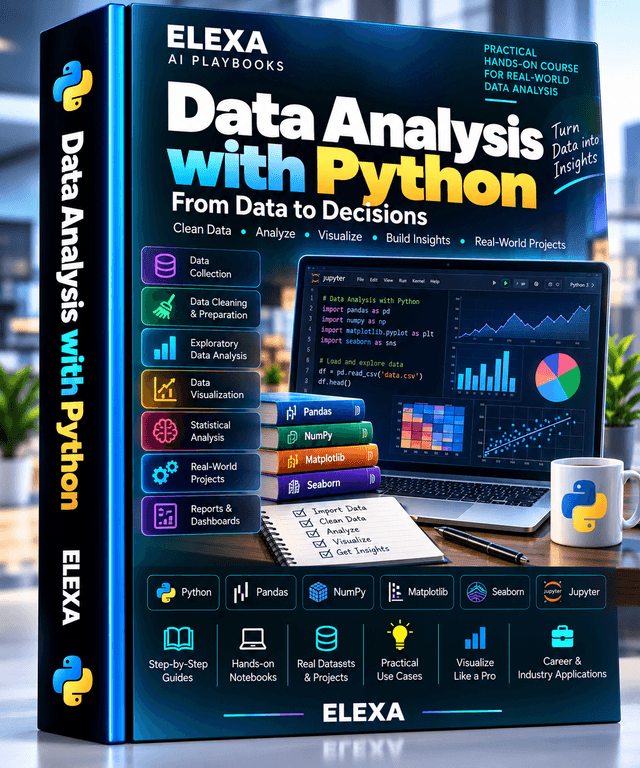
Every AI and Machine Learning project starts with data, and most of the work is understanding it. This playbook teaches you how to load real datasets, clean them, explore them and present what you find, using the same Python tools data analysts and data scientists use every day.
Each chapter starts with a real question, such as which products sell best or when customers stop buying. You then work through the data step by step to answer it. Every concept is explained in plain language before the code, and every chapter comes with annotated code, a checklist and AI prompts to help you practise.
What you will build
You work on realistic datasets such as sales records and customer data. By the end you have built a sales analysis with charts, a customer insights report and a reusable analysis notebook you can apply to your own data. All notebooks and source code are included.
What the playbook covers
You start with Jupyter Notebook and the basics of NumPy, then spend most of the playbook with Pandas: loading CSV and Excel files, selecting and filtering rows, handling missing values, fixing data types and removing duplicates. You then group, aggregate, merge and reshape data to answer business questions. The final chapters cover visualisation with Matplotlib and Seaborn, exploratory data analysis and presenting your findings in a clear report.
Who this playbook is for
It is for people who know basic Python and want to work with real data. It suits aspiring data analysts and data scientists, developers who want to add data skills, and professionals who work with spreadsheets and want to go further with Python.
Where it leads
Data analysis is the step between Python and Machine Learning on the Elexa AI Learning Path. The cleaning, exploring and feature skills you practise here are exactly what you use to prepare data for Machine Learning models in the next playbook.